
Comprehensive Coverage of R2V Tasks
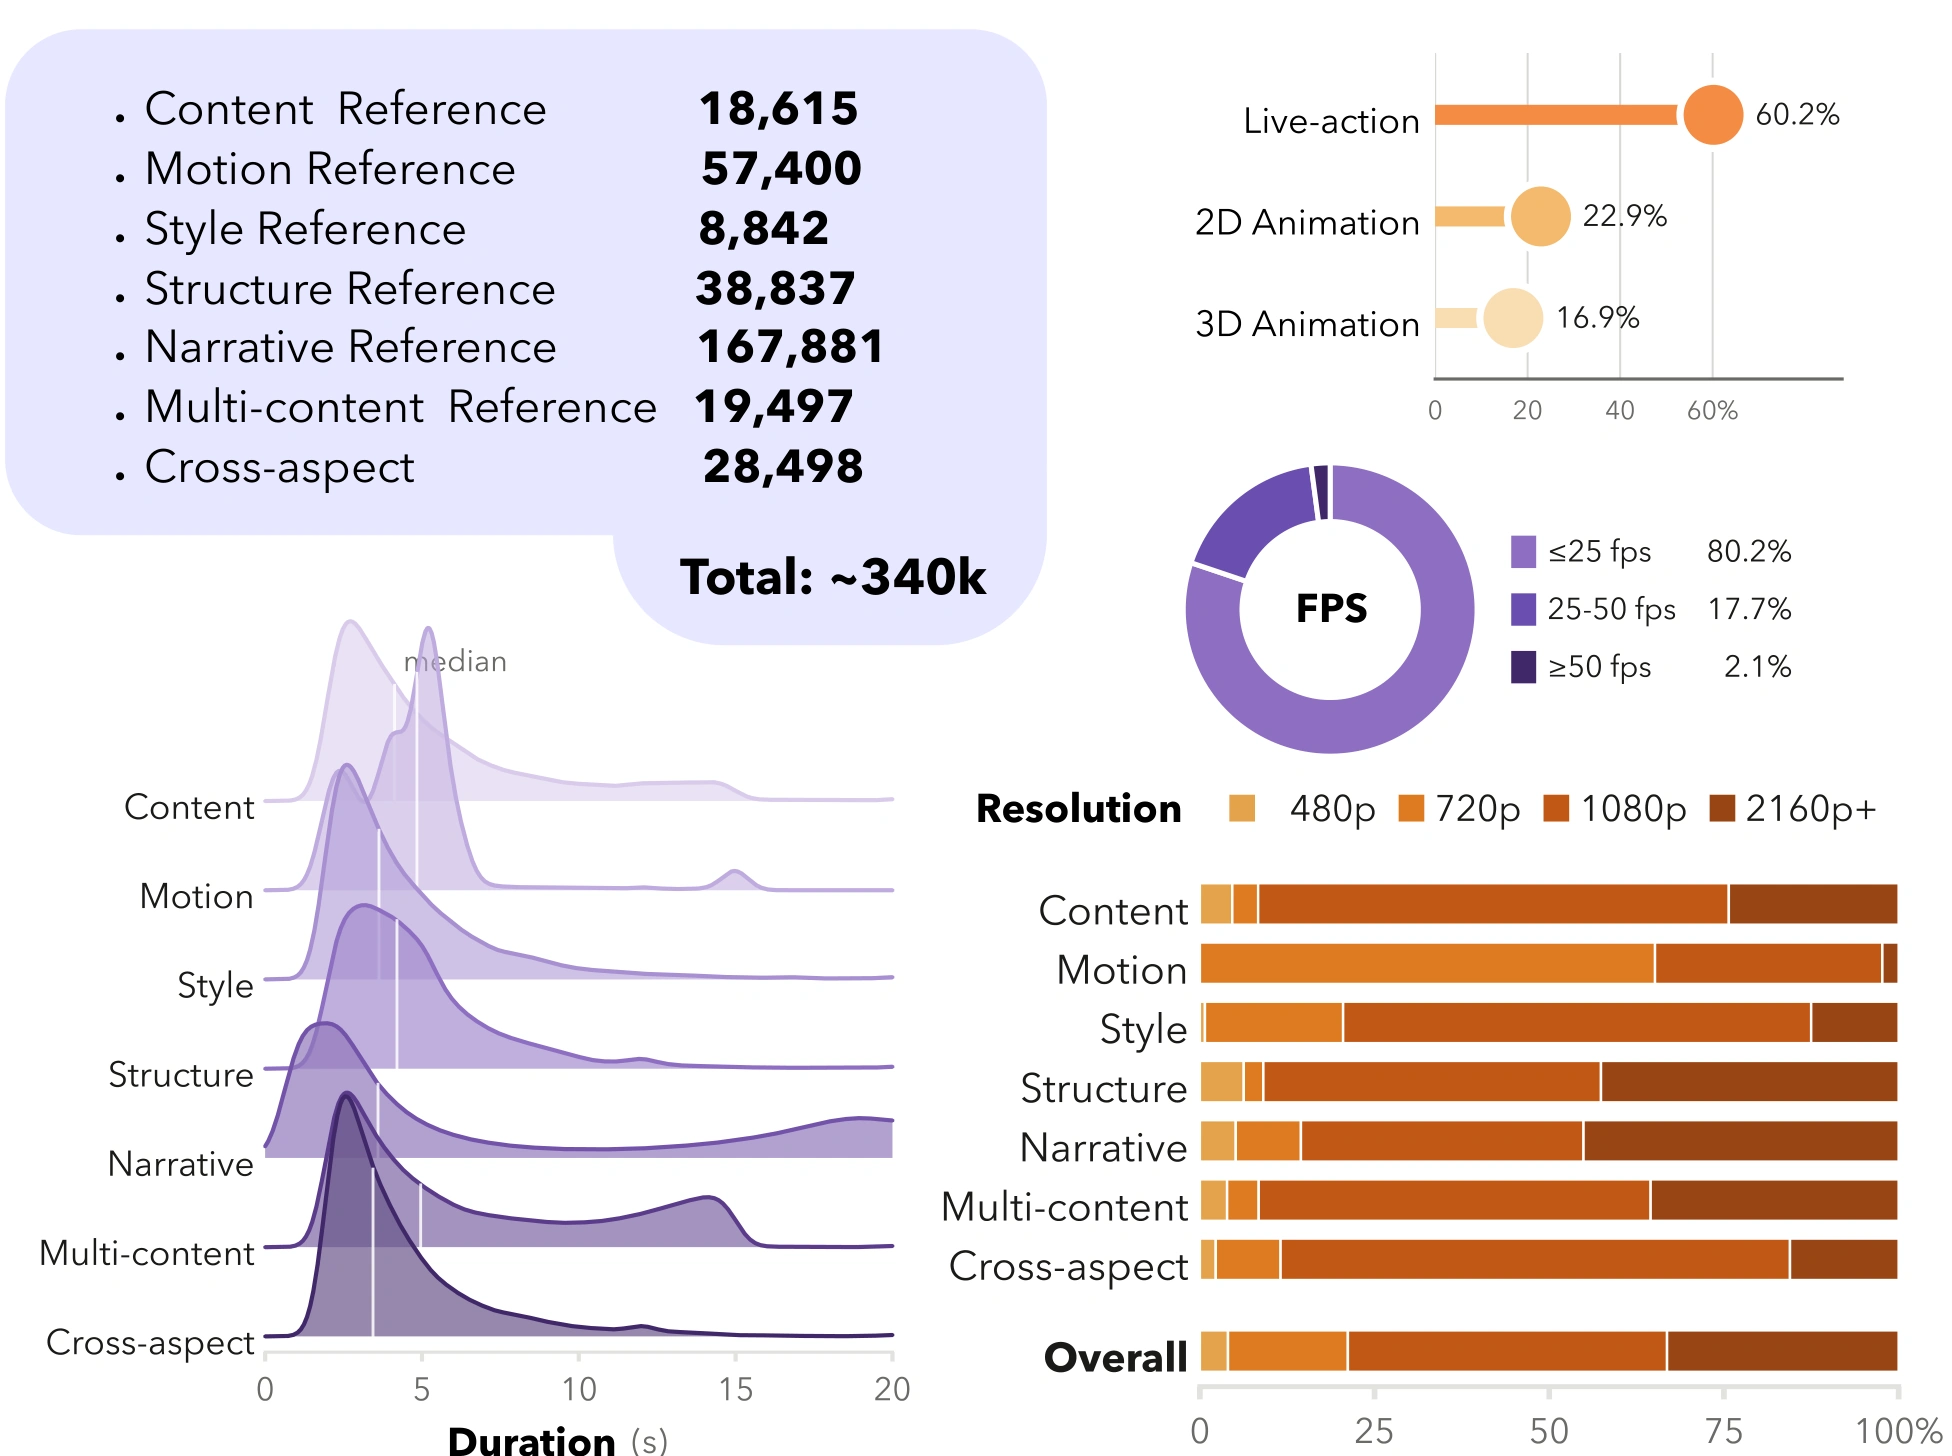
The first large-scale public R2V training dataset covering heterogeneous reference types across seven task families, spanning single-reference tasks and multi-reference compositions.
REFERENCE-TO-VIDEO GENERATION
A benchmark and large-scale dataset
for omni reference-to-video generation.
The first large-scale public R2V training dataset covering heterogeneous reference types across seven task families, spanning single-reference tasks and multi-reference compositions.
340K processed training samples built primarily from professional video footage, spanning live-action, 2D animation, and 3D animation.
Task-specific pipelines construct reference–target pairs and corresponding training instructions, providing a reusable recipe for omni-R2V data construction.
| Dataset | # Size | Reference Modality | Reference Task Coverage | Processed Data Provided | |||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| Image | Video | Content | Motion | Style | Structure | Narrative | Multi-Content | Cross-Aspect | |||
| OpenS2V-5M | 5.4M | ✓ | ✓ | ✓ | ✓ | ||||||
| Phantom-Data | 1M | ✓ | ✓ | ✓ | |||||||
| MuSS | 30K | ✓ | ✓ | ||||||||
| Omni-R2V (Ours) | 340K | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
Omni-R2V is the only dataset providing processed image and video references across all seven task families.
@article{omnivbench2026,
  title   = {OmniVBench: A Benchmark and Large-Scale Dataset for Omni Reference-to-Video Generation},
  author  = {Li, Wenxue and Guan, Peiyan and Jiang, Haoyang and Cai, Junxian and
             Liu, Hualuo and Zhang, Chunjie and Guan, Chong and Huang, Kai and
             Li, Songlian and
             Wu, Taiyi and Yu, Yongjian and Zhao, Xiaotong and
             Zhao, Alan and Liu, Eric and Chen, Xi and Liu, Yu and Zhu, Lei},
  journal = {arXiv preprint arXiv:2609.22069},
  year    = {2026},
  url     = {https://arxiv.org/abs/2609.22069}
}